
LLM Integration & Engineering
Production wiring for large language models: RAG, tools, gateways, evals, and cost control inside your applications.
Talk to an expert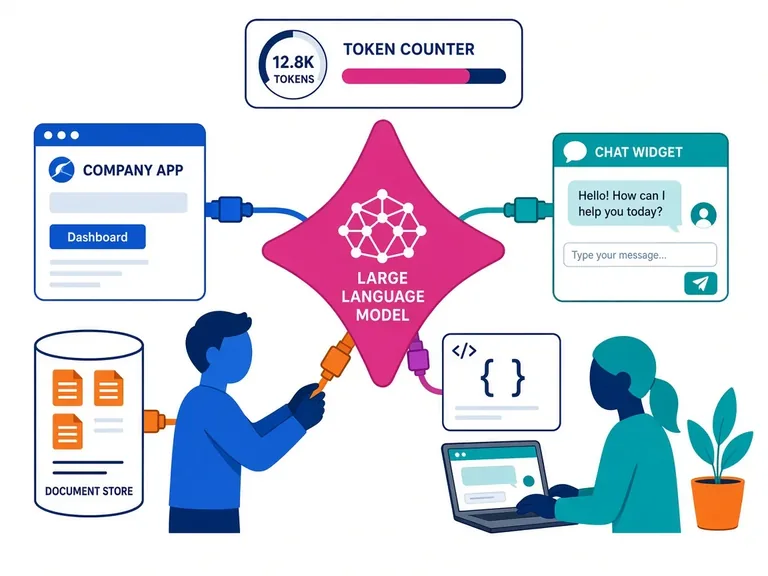
The offering
What we actually deliver
LLM engineering is the unglamorous layer between a model API and a product: retrieval, tool calling, prompt and schema versioning, rate limits, fallbacks, and tracing. We build that layer in your stack so product teams do not each invent a gateway. Providers can be swapped; prompts are not hardcoded in a frontend.
Retrieval is designed as a search problem — chunking, metadata, freshness, permissions — not as 'dump the drive into a vector store'. Tool calling is allow-listed. Outputs that must be structured are validated. Eval harnesses run on pull requests when prompts change. Cost and latency budgets are real: we will cap tokens and cache when the use case allows.
Security is boring and required. Secrets, DLP, and 'this tenant cannot see that corpus' are tested. We prefer private networking to the model provider when you already require it for other SaaS.
You get a platform slice or a service inside an app that product squads can call, with docs and a cost dashboard. The model is a dependency. The engineering is the product. Prompt and schema versions ship through the same pipeline as application code, so a prompt change is reviewed, evaluated, and roll-backable instead of edited live against production traffic.
What you get
How we work
A delivery path you can follow
Each engagement is sequenced so architecture, cutover, and handover are visible — not a black box at the end.
Talk to us about LLM Integration & Engineering
Share the current estate, deadline, and constraints — we will tell you what a first engagement should contain.